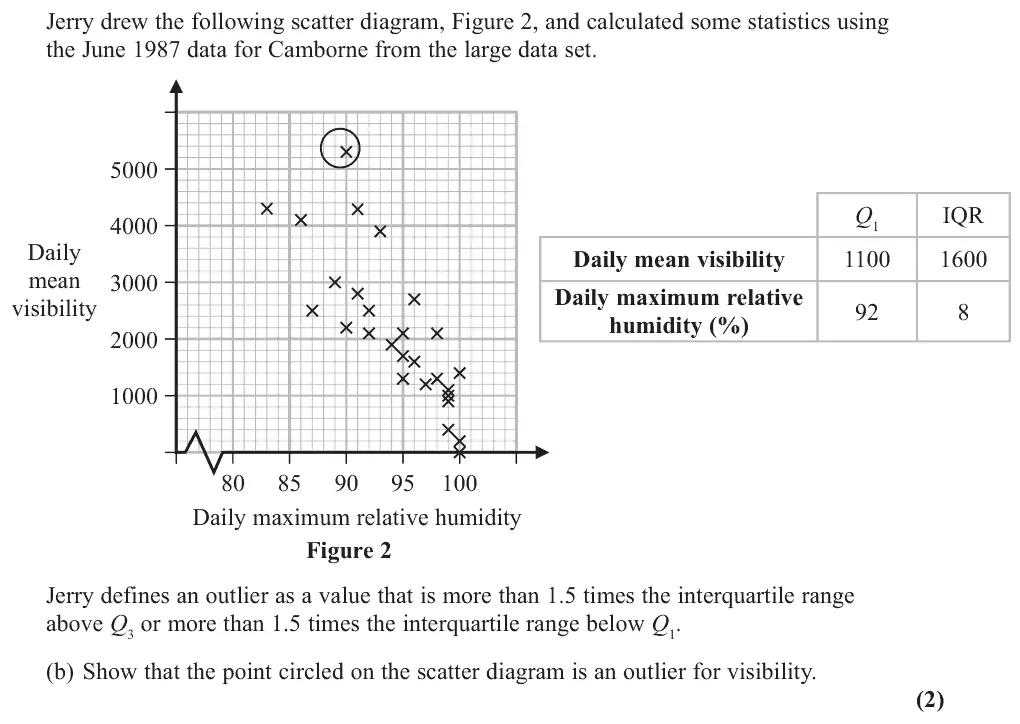
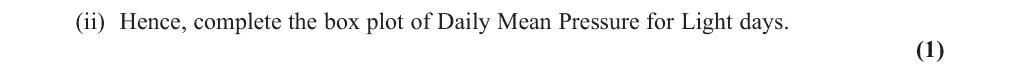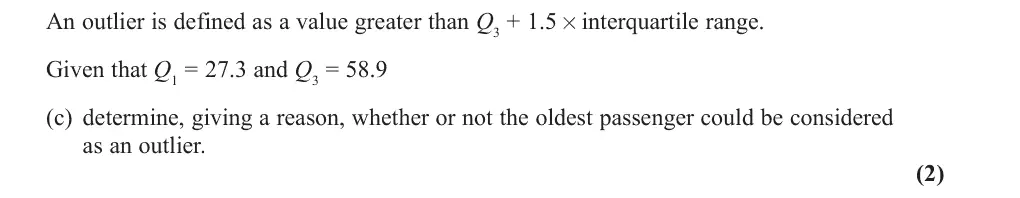Recognise and interpret possible outliers in data sets and statistical diagrams. Select or critique data presentation techniques in the context of a statistical problem. Be able to clean data, including dealing with missing data, errors and outliers.
Guidance
Any rule needed to identify outliers will be specified in the question, for example use of Q₁ − 1.5 × IQR and Q₃ + 1.5 × IQR, or mean ± 3 × standard deviation. Students will be expected to draw simple inferences and give interpretations to measures of central tendency and variation. Significance tests, other than those mentioned in Section 5, will not be expected. For example, students may be asked to identify possible outliers on a box plot or scatter diagram.
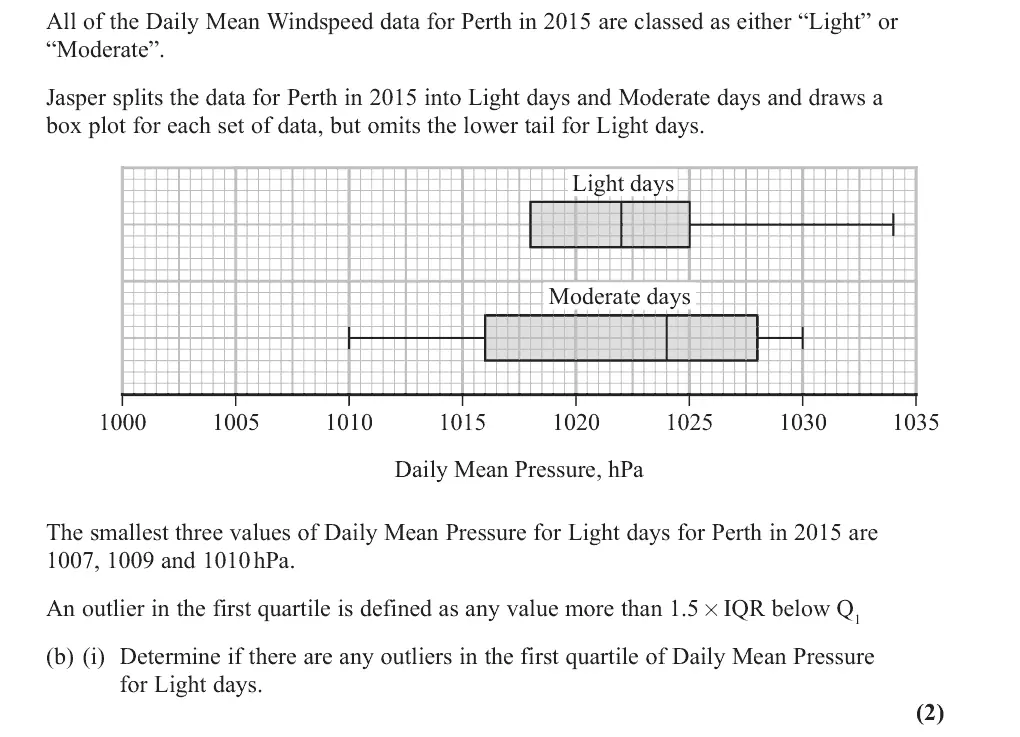
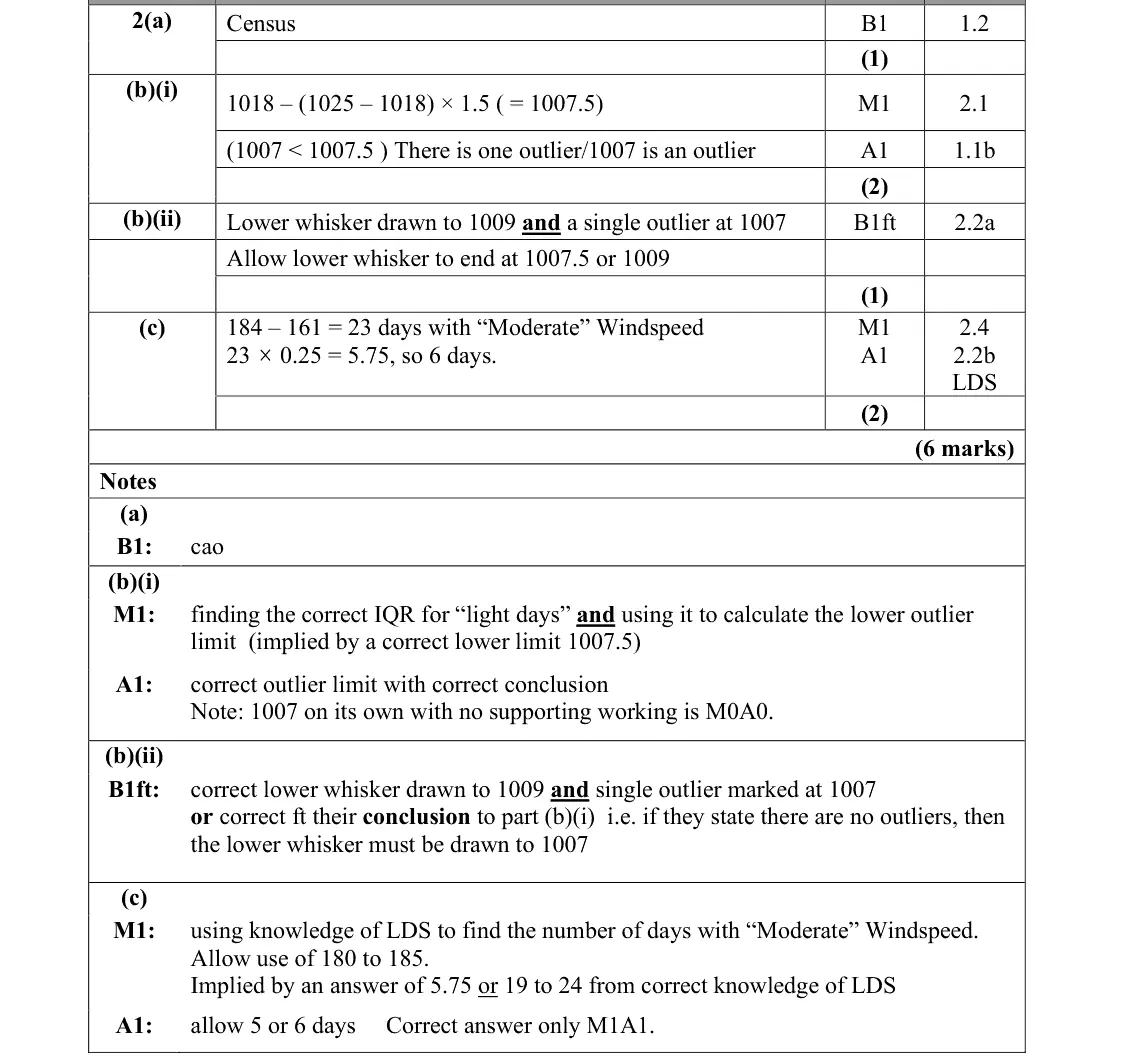
June 2025 · AS Paper 2 (Statistics) · Q2(b)(i)2 marks
Mark scheme (whole question; this part is marked with the orange bar)
Examiner's comment
Most students were able to complete part (b)(i), calculating the lower outlier limit correctly and then showing that 1007 was an outlier. The most common mistakes were calculating 1007.5 but then concluding there were no outliers or only finding the IQR and thus attaining no marks. The drawing of outliers on a boxplot caused problems, with many students getting (b)(i) correct but then being unable to illustrate this correctly on the box plot. Often students made bottom whisker end at 1009 but did not mark in the outlier. There was also a significant minority who were unable to read the scale correctly when plotting values. There was follow through available in (b)(ii) for those who made a slip calculating the lower outlier limit in
Common mistakes
read Q1 = 1018 and Q3 = 1025 from the box plot
limit 1018 − 1.5 × 7 = 1007.5
conclude 1007 is the only outlier (1007 alone with no working scores 0)
some found 1007.5 then said there were no outliers, or found only the IQR
June 2025 · AS Paper 2 (Statistics) · Q2(b)(ii)1 mark
Mark scheme (whole question; this part is marked with the orange bar)
Examiner's comment
through available in (b)(ii) for those who made a slip calculating the lower outlier limit in part (i).
Common mistakes
lower whisker to 1009 (1007.5 allowed) and a single outlier marked at 1007
many drew the whisker but did not mark the outlier, or misread the scale
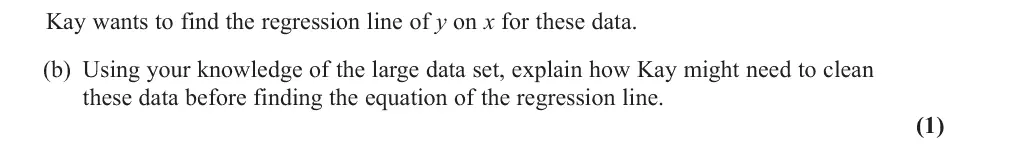
June 2025 · Paper 3 (Statistics) · Q4(b)1 mark
Mark scheme (whole question; this part is marked with the orange bar)
Examiner's comment
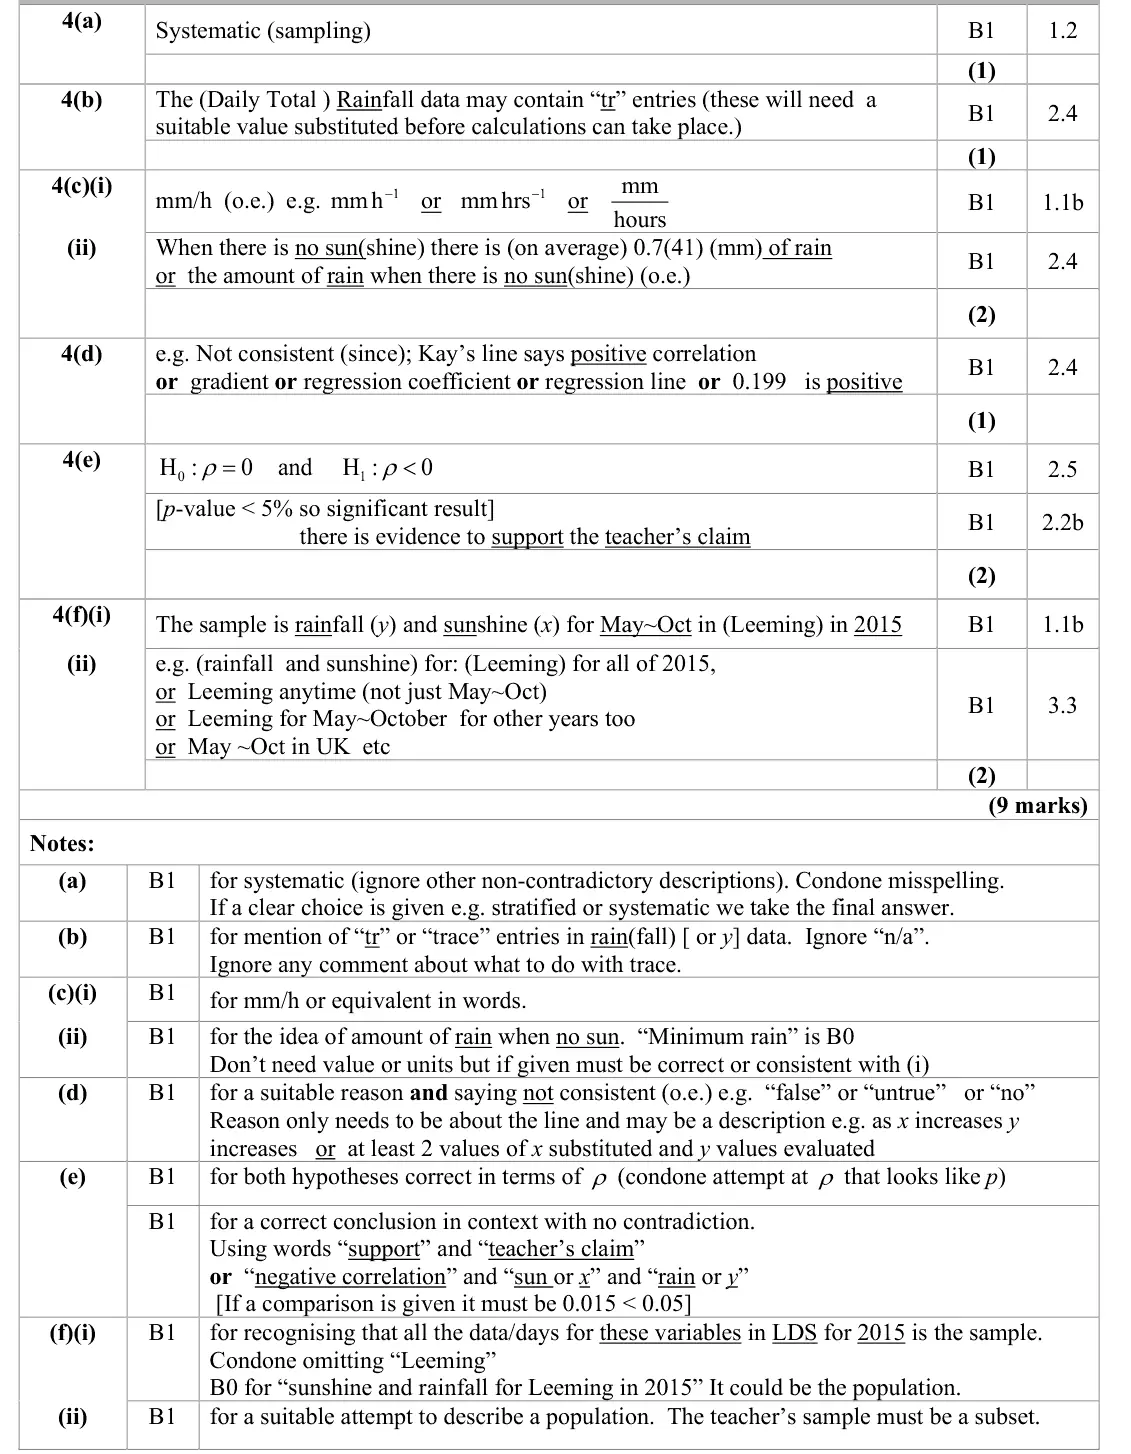
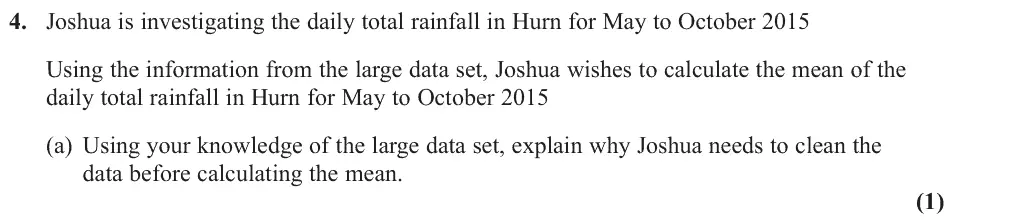
In part (b) most identified that “trace” or “tr” would need attention, but some did not link this to the rainfall variable. In part (c) (i) there were many correct answers and some who
Common mistakes
daily total rainfall may contain "tr" (trace) entries that need a value before calculating
must link it to rainfall
June 2024 · AS Paper 2 (Statistics) · Q2(a)1 mark
Mark scheme (whole question; this part is marked with the orange bar)
Examiner's comment
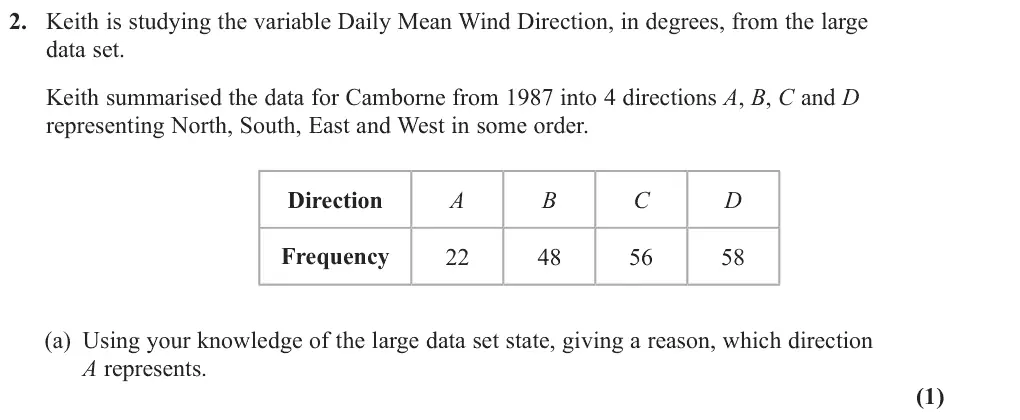
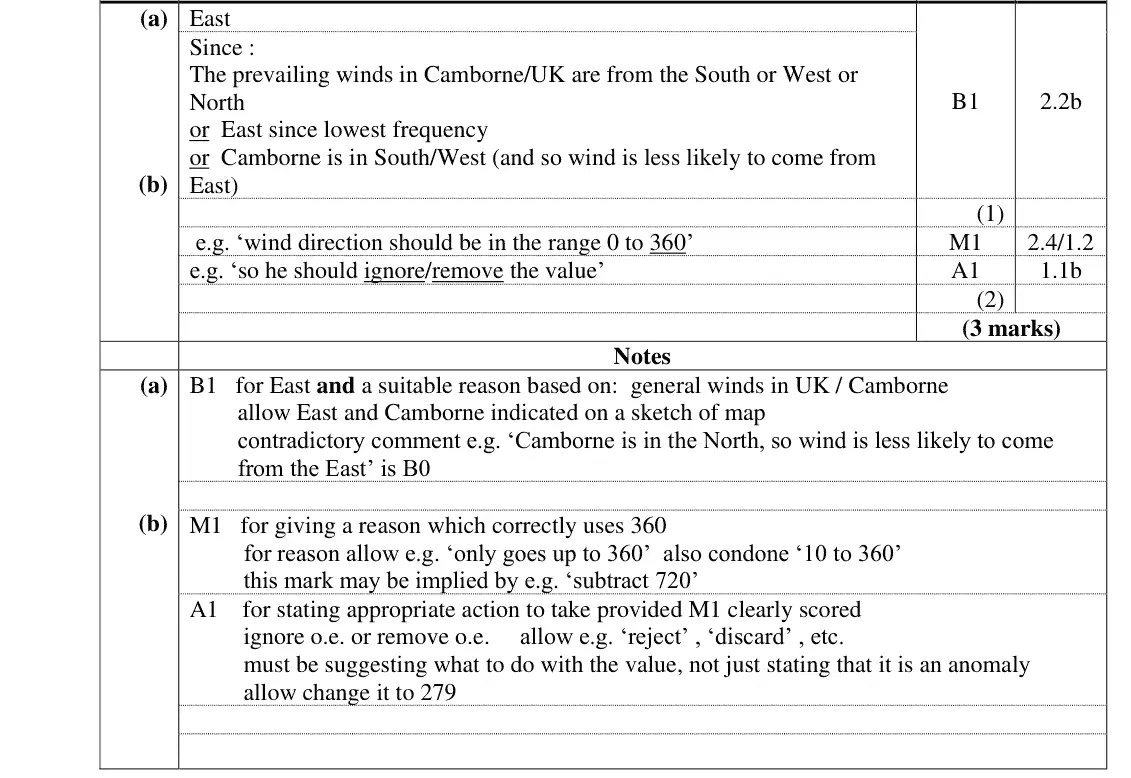
This question was generally not well attempted demonstrating that students are still not completely familiar with the large data set. In part (a) many students appeared to be aware of Camborne's location in the South-West of the UK but could not relate this to the prevailing winds in that area. Some students were able to guess that A represented East but were unable to provide a reason. Many students did not appreciate that wind direction is the direction that wind blows from, rather than to.
Common mistakes
A is East: the least common direction, since prevailing UK/Camborne winds come from the south-west (west/south)
wind direction is where the wind blows from, not to
a reason is needed
June 2024 · AS Paper 2 (Statistics) · Q2(b)2 marks
Mark scheme (whole question; this part is marked with the orange bar)
Examiner's comment
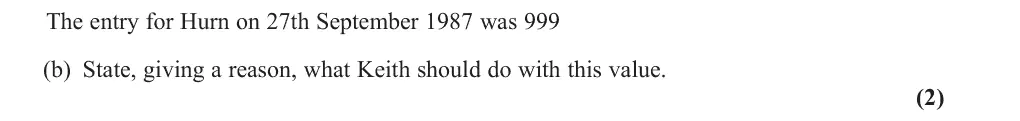
This question was generally not well attempted demonstrating that students are still not In part (b), many students appreciated that the value was an outlier and should be excluded but were unable to score the marks here without justification. Those who understood that the maximum that the angle could be 360, tended to score well here. Some students also thought that 999 represented a frequency rather than an angle.
Common mistakes
wind direction runs from 0 to 360 degrees so 999 is not a valid value (it is an error/missing-data code, not an outlier or a frequency)
remove/ignore it
a reason using 360 is needed before the action
June 2024 · Paper 3 (Statistics) · Q3(a)1 mark
Mark scheme (whole question; this part is marked with the orange bar)
Examiner's comment
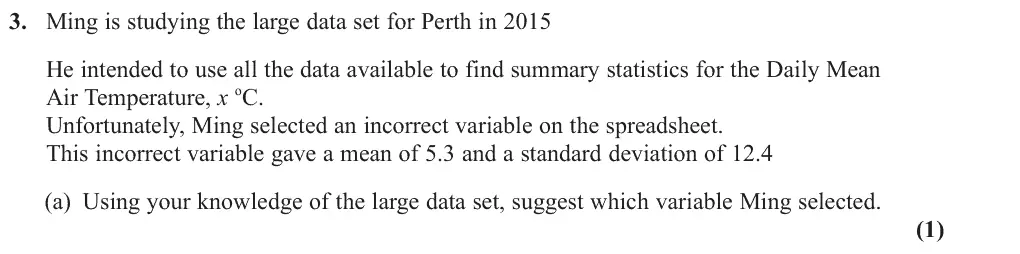
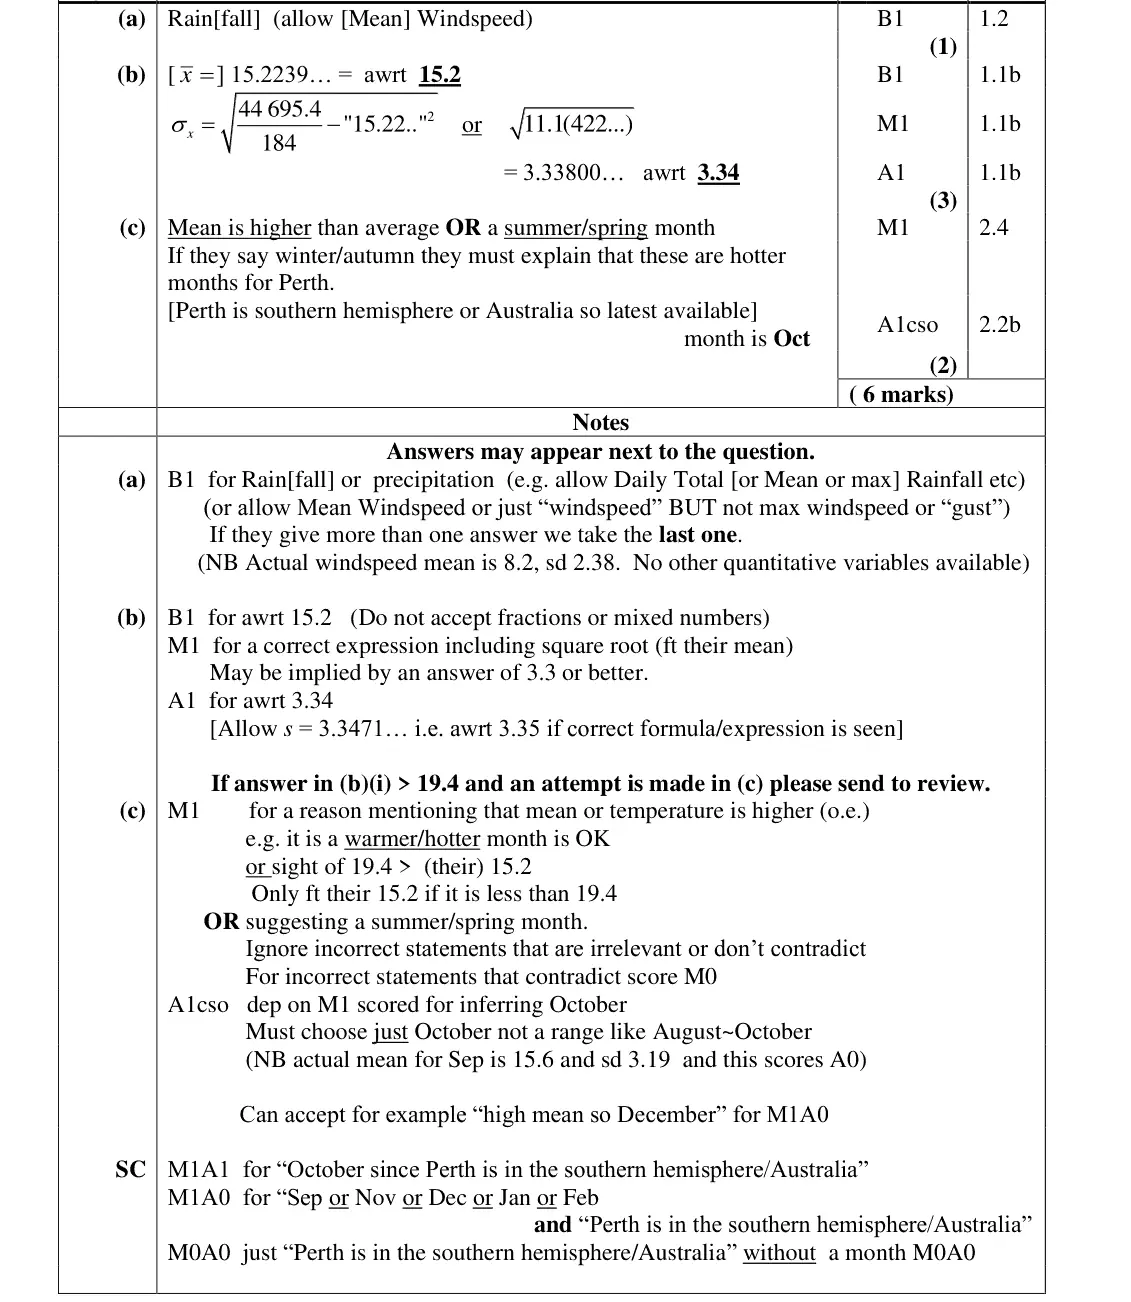
It is encouraging to see most students now attempting the question on the large data set and a growing familiarity with it. In part (a) many wrote down rainfall or windspeed but other quantitative variables such as hours of sunshine or maximum wind gust were sometimes seen but these are not variables available for overseas locations. Some students gave answers like “trace” or “outlier” which have appeared in previous papers but had no relevance to this question. Part (b) was a
Common mistakes
rainfall (or mean windspeed)
hours of sunshine and gusts are not recorded for overseas locations
"trace" or "outlier" irrelevant here
June 2023 · AS Paper 2 (Statistics) · Q2(d)1 mark
Mark scheme (whole question; this part is marked with the orange bar)
Examiner's comment
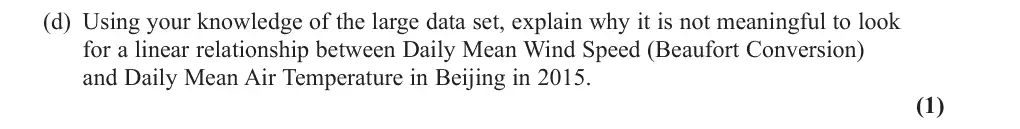
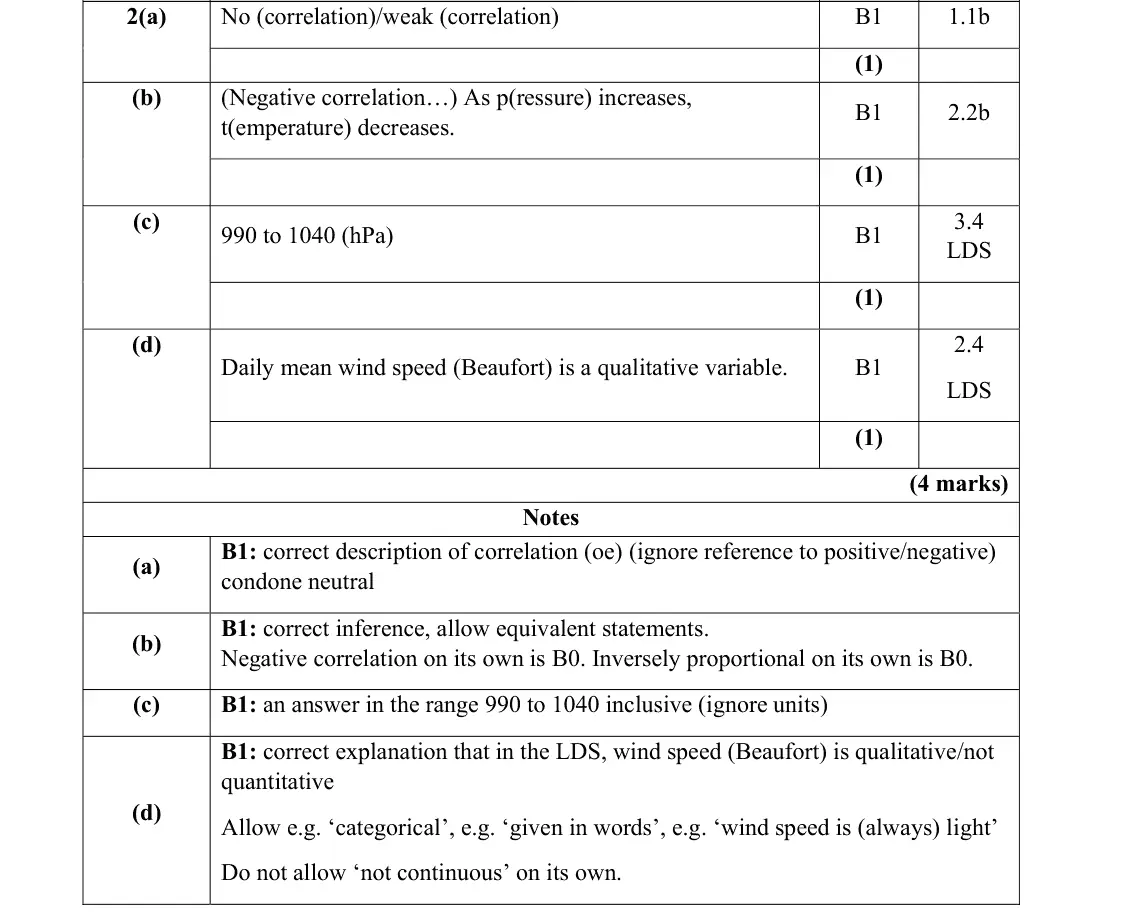
but due to parts (c) and (d) requiring familiarity with the large data set, only a small minority of students scored full marks here. Most students successfully answered part (a) with a correct interpretation of a lack of standard in parts (c) and (d) was poor. Most students guessed an answer to part (c) but very few were able to give an answer in the correct range. In part (d), the students often described the location of Beijing as a factor or repeated an answer given in previous examination series rather than comment on the Beaufort Conversion being qualitative data. It was clear the students who had studied the large data set as their answers had a concise explanation.
Common mistakes
Daily Mean Wind Speed (Beaufort Conversion) is qualitative/categorical (given in words)
"not continuous" alone not accepted
location of Beijing is not a reason
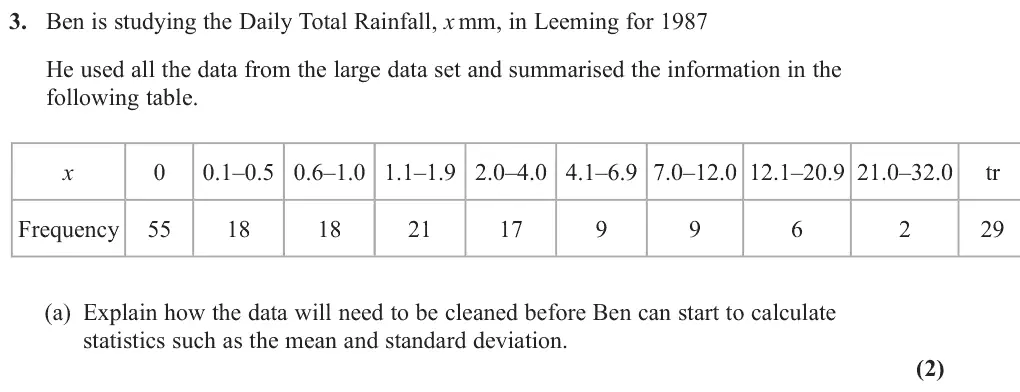
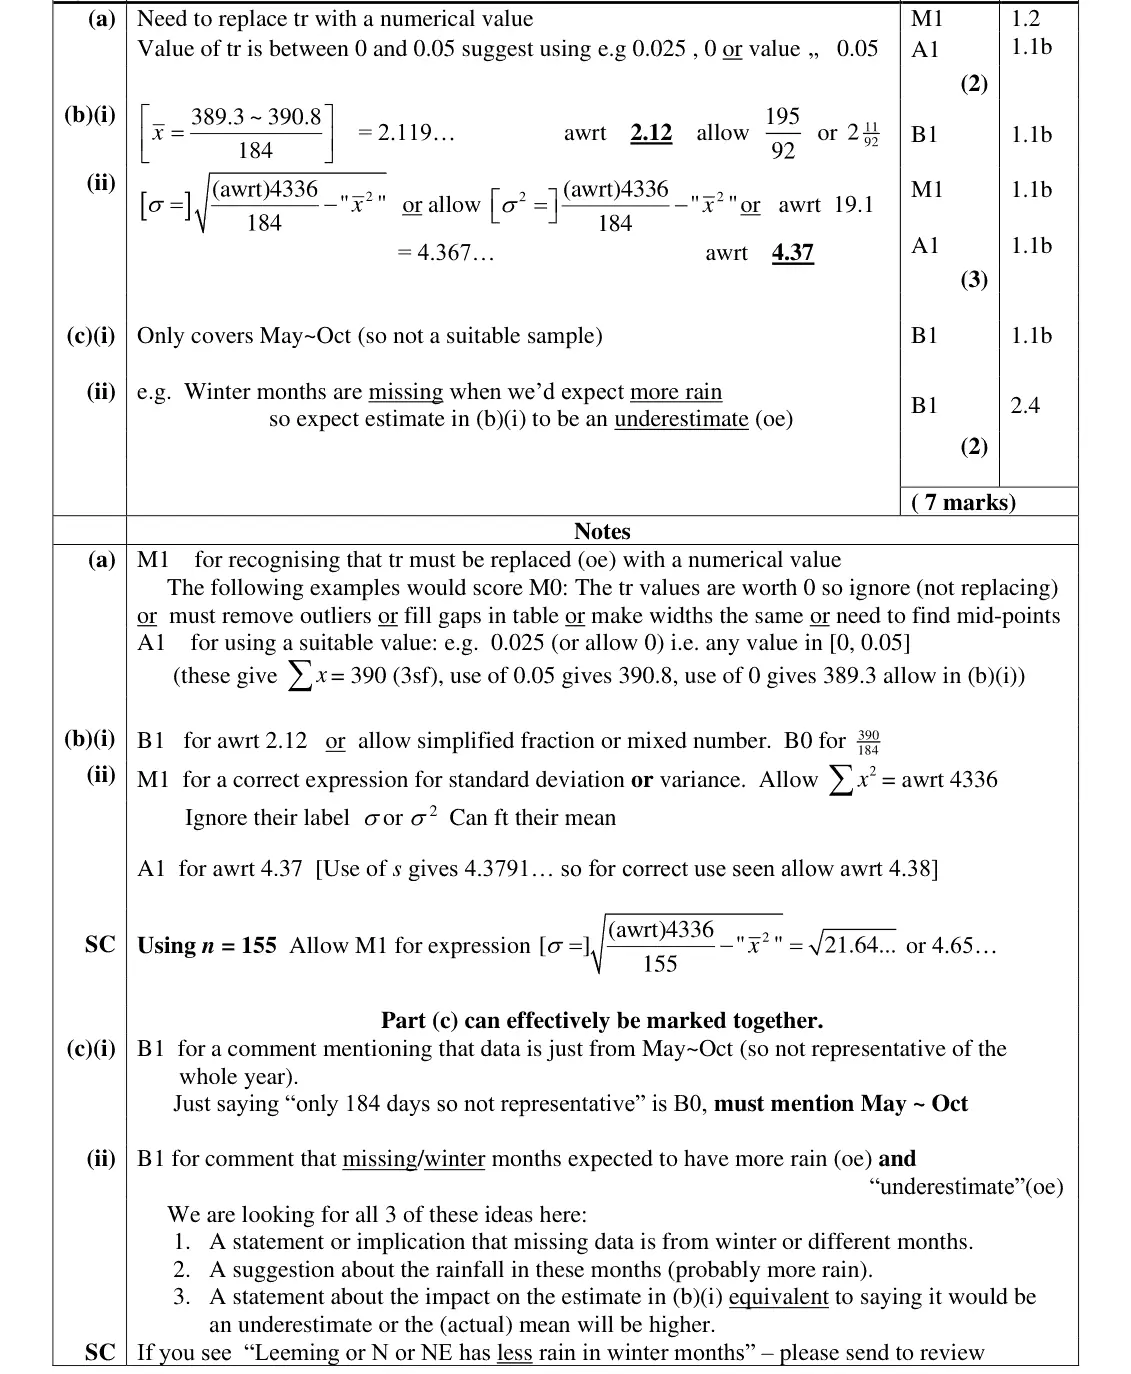
June 2023 · Paper 3 (Statistics) · Q3(a)2 marks
Mark scheme (whole question; this part is marked with the orange bar)
Examiner's comment
Once again the large data set aspects of this question caused problems for some students but most scored some marks here. In part (a) a few responses simply quoted standard textbook answers about cleaning data by removing outliers and others were distracted by the class intervals for the data. Many though did realise that the “tr” values needed attention but a number didn’t seem to realise that trace entries had a value between 0 and 0.05 and therefore removing them would have a big effect on the calculations Ben wanted to carry out. Those that did appreciate the value of the “tr” usually suggested a suitable numerical value (usually 0) to replace them with and scored both marks.
Common mistakes
tr (trace) means less than 0.05 mm: replace with a numerical value such as 0 or 0.025, do not remove
removing outliers or equalising class widths is not cleaning here
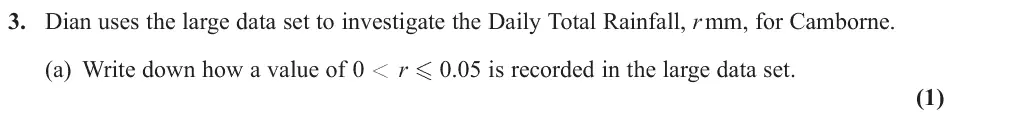
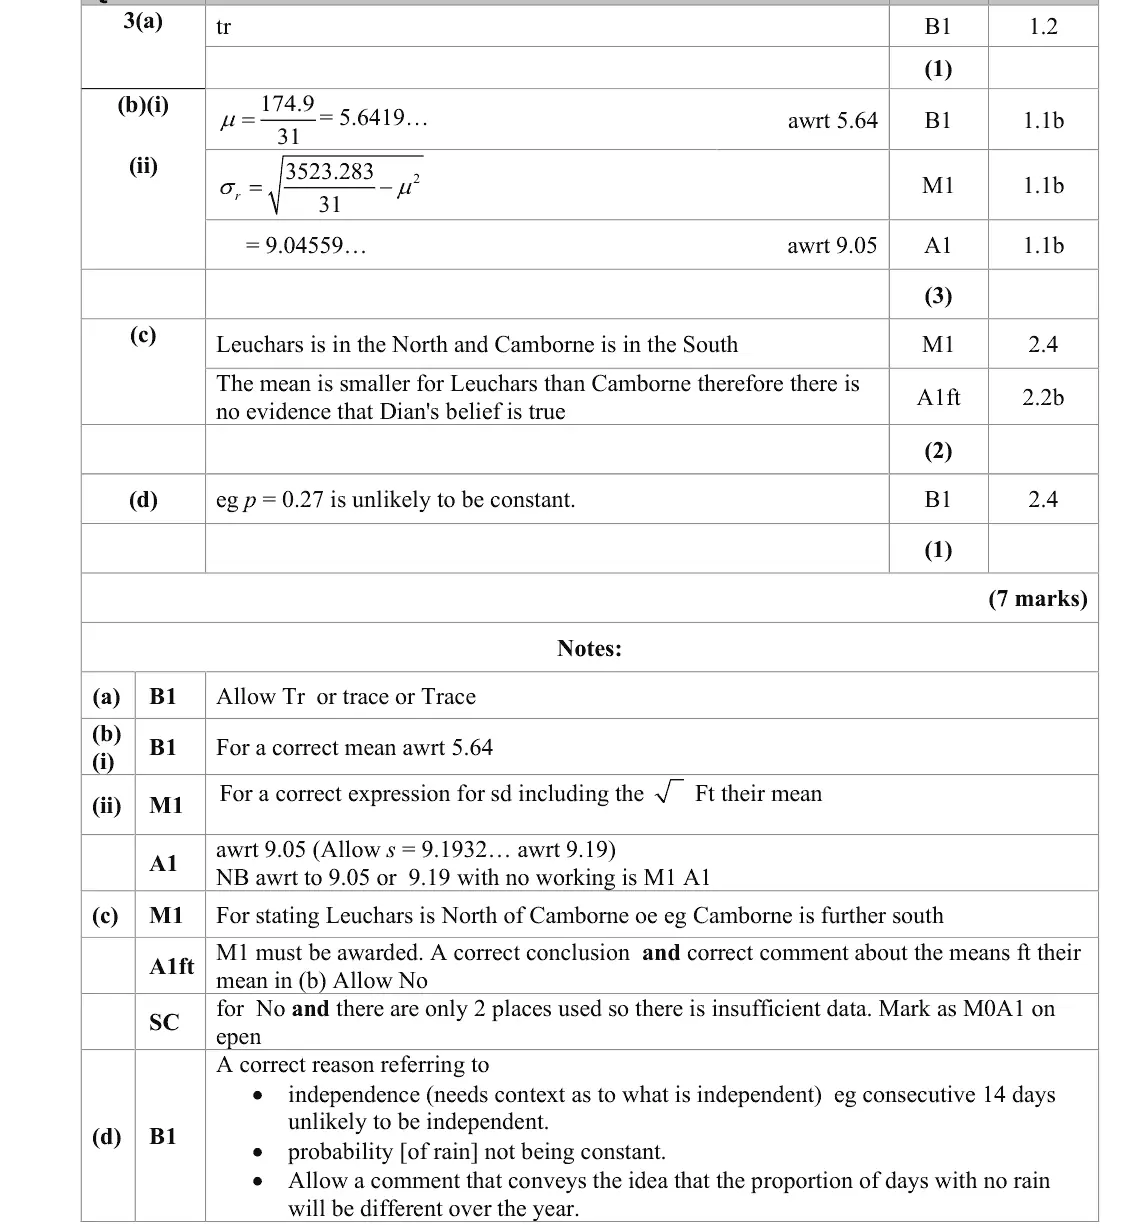
June 2022 · Paper 3 (Statistics) · Q3(a)1 mark
Mark scheme (whole question; this part is marked with the orange bar)
Examiner's comment
Part (a) tested knowledge of the data set. Some students were able to identify tr or trace as the required answer, but many displayed their lack of knowledge of the data set, with n/a being a typical wrong answer, or 0 or 0.025. Many students gave no answer of any sort and there were a few nonsensical or confused answers such as explaining how the rainfall might be collected (a particular favourite being ‘with a bucket and ruler’) or how it might be recorded (in an excel spreadsheet).
Common mistakes
tr (trace)
n/a, 0 or 0.025 are wrong
Oct 2021 · AS Paper 2 (Statistics) · Q2(c)2 marksEasy
Mark scheme (whole question; this part is marked with the orange bar)
Examiner's comment
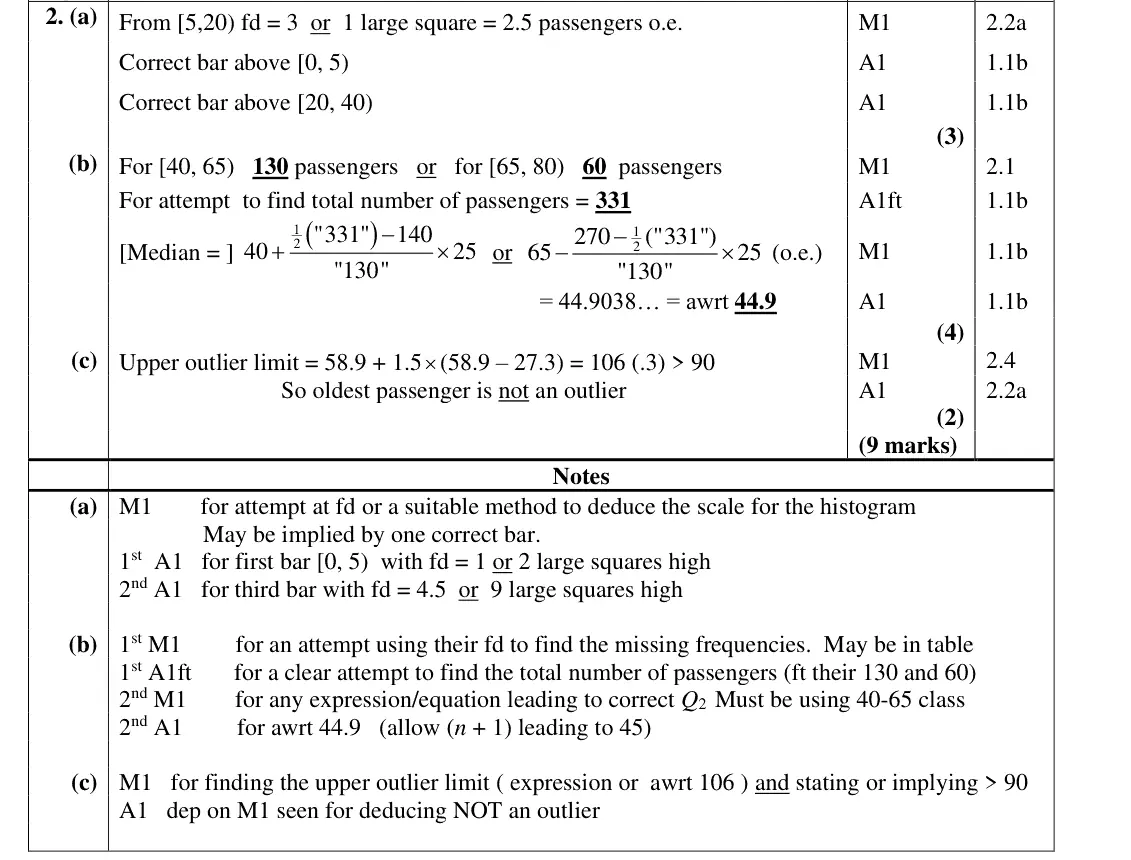
The response to this question on histograms was much better than in previous series with over 50% scoring 7 or more marks. Most managed to complete at least one of the bars of the histogram correctly but a some errors in class boundaries and a fair number of very confused attempts. In part (c) most were able to find the upper outlier limit but some were not able to explain clearly why they could then deduce that none of the passengers were outliers. We required a clear statement that none of the passengers were over 90 and 90 was less than this limit so there were no outliers.
Common mistakes
upper limit 58.9 + 1.5 × 31.6 = 106.3
must state that no passenger is 90 or over and 90 < 106 so the oldest is not an outlier
Oct 2020 · AS Paper 2 (Statistics) · Q2(a)1 mark
Mark scheme (whole question; this part is marked with the orange bar)
Examiner's comment
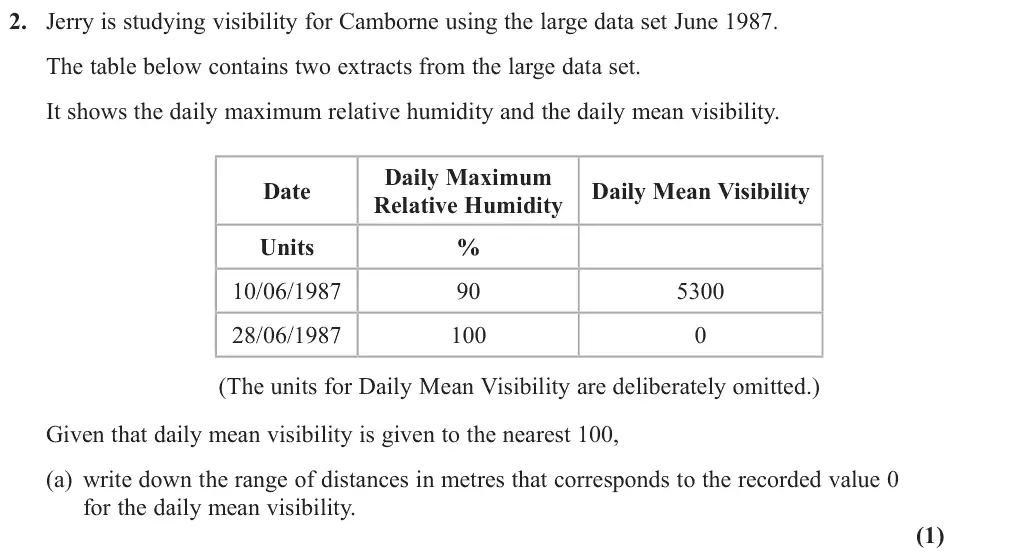
It was clear from the responses seen here that many candidates have little or no experience with the large data set. In part (a) very few students knew that the figures for Daily Mean Visibility are in decametres (Dm). In part (d) a minority of
Common mistakes
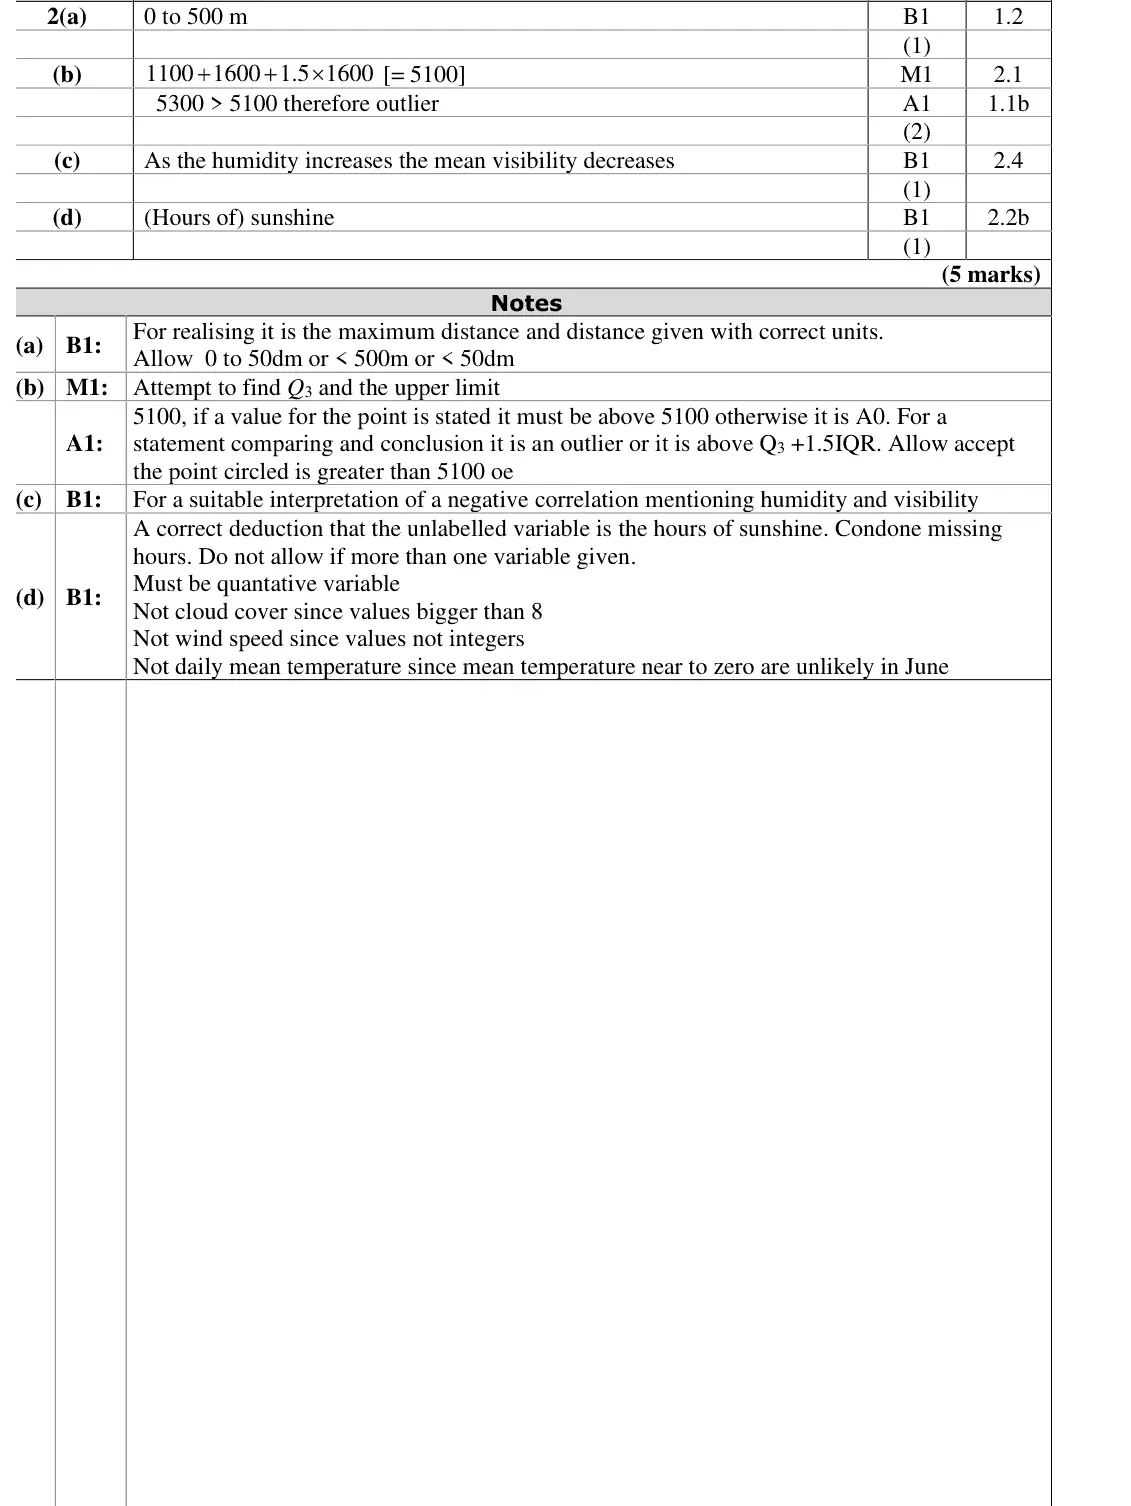
visibility in the large data set is in decametres, so 0 to the nearest 100 dam means 0 to 500 m (or under 50 dam)
very few knew the units
Oct 2020 · AS Paper 2 (Statistics) · Q2(b)2 marks
Mark scheme (whole question; this part is marked with the orange bar)
Examiner's comment
It was clear from the responses seen here that many candidates have little or no In part (b) most candidates who produced an answer were able to gain some marks. The most common mistake was to multiply the LQ by 3 in order to find the UQ. A few candidates calculated the upper boundary correctly, but then failed to make a comparison to finish off their reasoning.
Mark scheme (whole question; this part is marked with the orange bar)
Examiner's comment
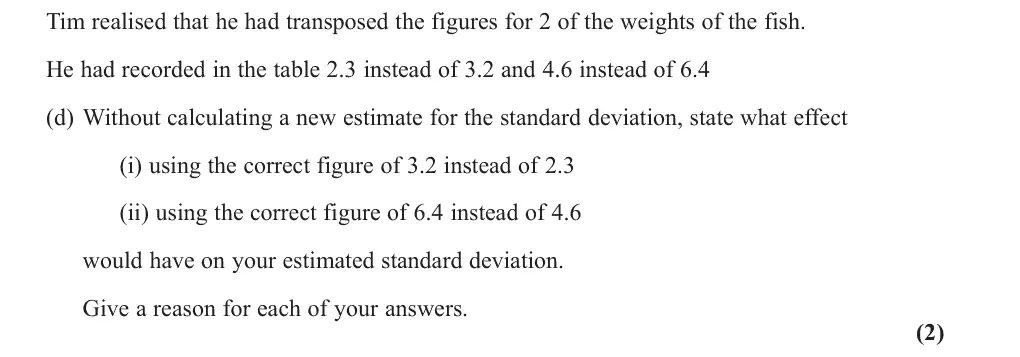
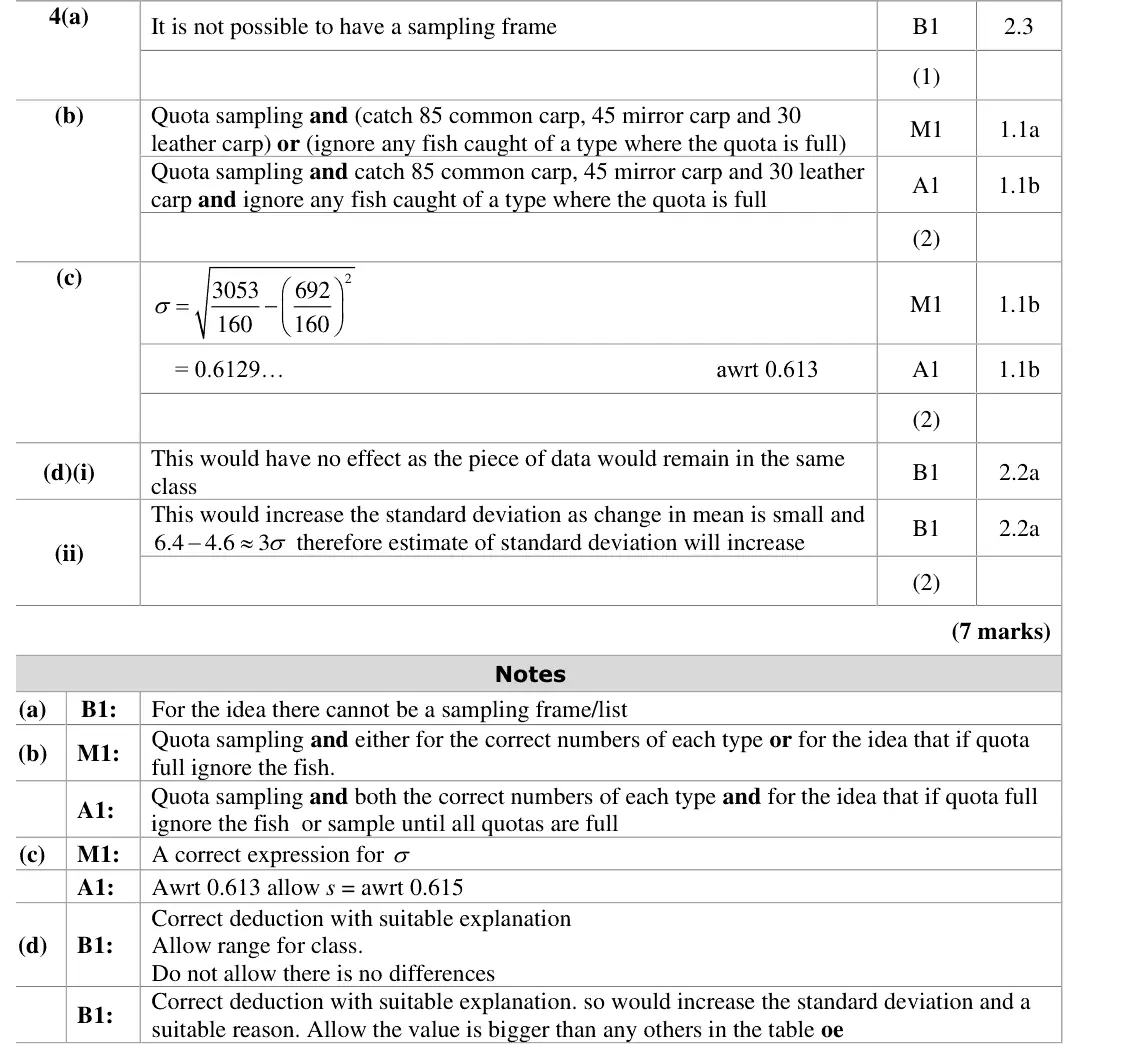
In part (d) it was very rare to see both parts answered correctly. Part(i) was answered the best, but even those who saw that the classes were important could not transfer this idea to the second part. Those candidates who realised the standard deviation will increase in (ii) were rarely able to give a good reason. Many simply stated the range increased but were unable to give an explanation as to why the range increased.
Common mistakes
(i) no effect: 2.3 and 3.2 are in the same class (2 to 3.5)
(ii) sd increases: 6.4 is further from the mean (about 3 sd) than any value / outside the classes
a reason is needed for each
Oct 2020 · Paper 3 (Statistics) · Q3(a)1 mark
Mark scheme (whole question; this part is marked with the orange bar)
Examiner's comment
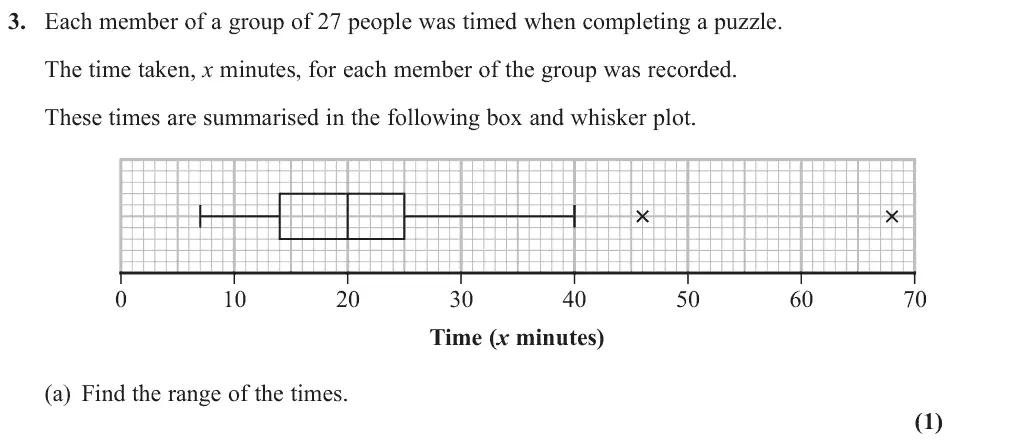
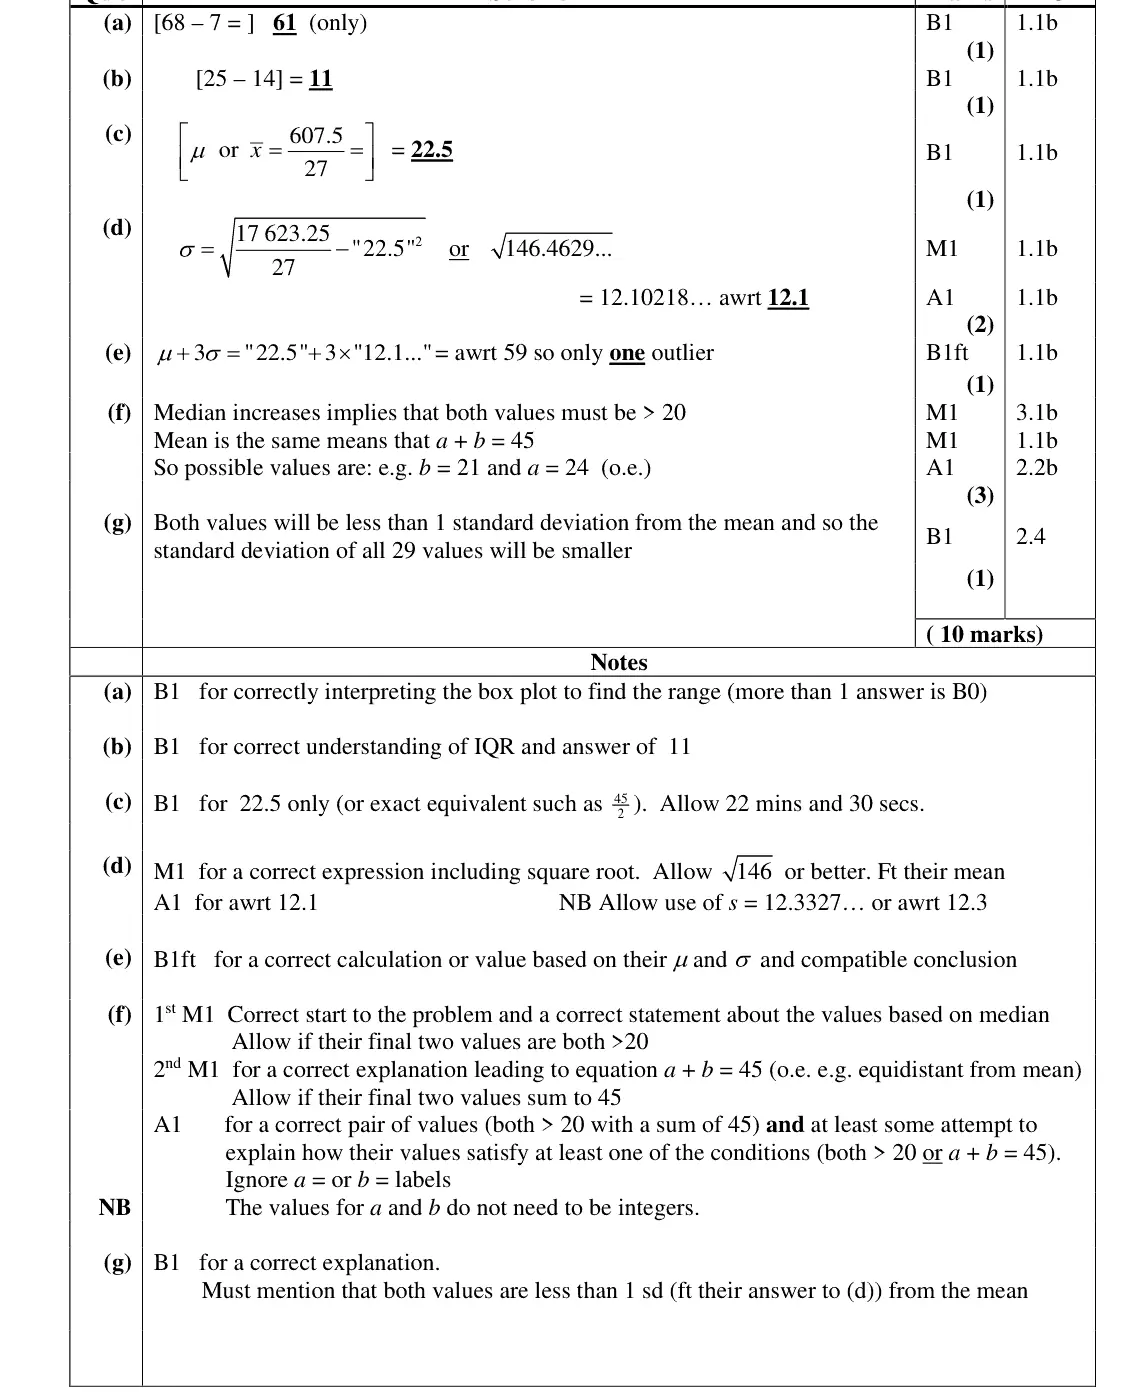
Part (a) should have been an easy start to the question but a surprisingly large number of students gave an answer of 33 by failing to consider the outliers to determine the range.
Common mistakes
range includes the outliers: 68 − 7 = 61, not 33
Oct 2020 · Paper 3 (Statistics) · Q3(e)1 mark
Mark scheme (whole question; this part is marked with the orange bar)
Examiner's comment
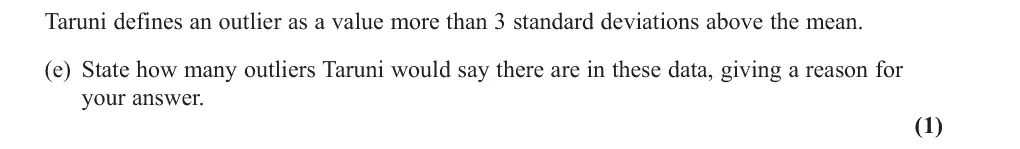
square root of failed to square the mean. In (e) most gave a suitable calculation to support their statement that Taruni would identify only 1 outlier. Some candidates used the median of 20 rather than the mean of 22.5 though. The last two parts were more challenging but it was encouraging to see a good number of attempts. Many were able to deduce that because the mean did not change then a + b = 45 but fewer were able to establish that, because the median increases, both values had to be greater than 20. Some did state these two conditions but sadly did not choose suitable values (a = 25 and b = 20 was a common error) for their final answer. In (g) many students stated that the
Common mistakes
mean + 3σ = 22.5 + 3 × 12.1 ≈ 59, so only one outlier (68)
use the mean 22.5, not the median 20
June 2019 · AS Paper 2 (Statistics) · Q4(a)1 mark
Mark scheme (whole question; this part is marked with the orange bar)
Examiner's comment
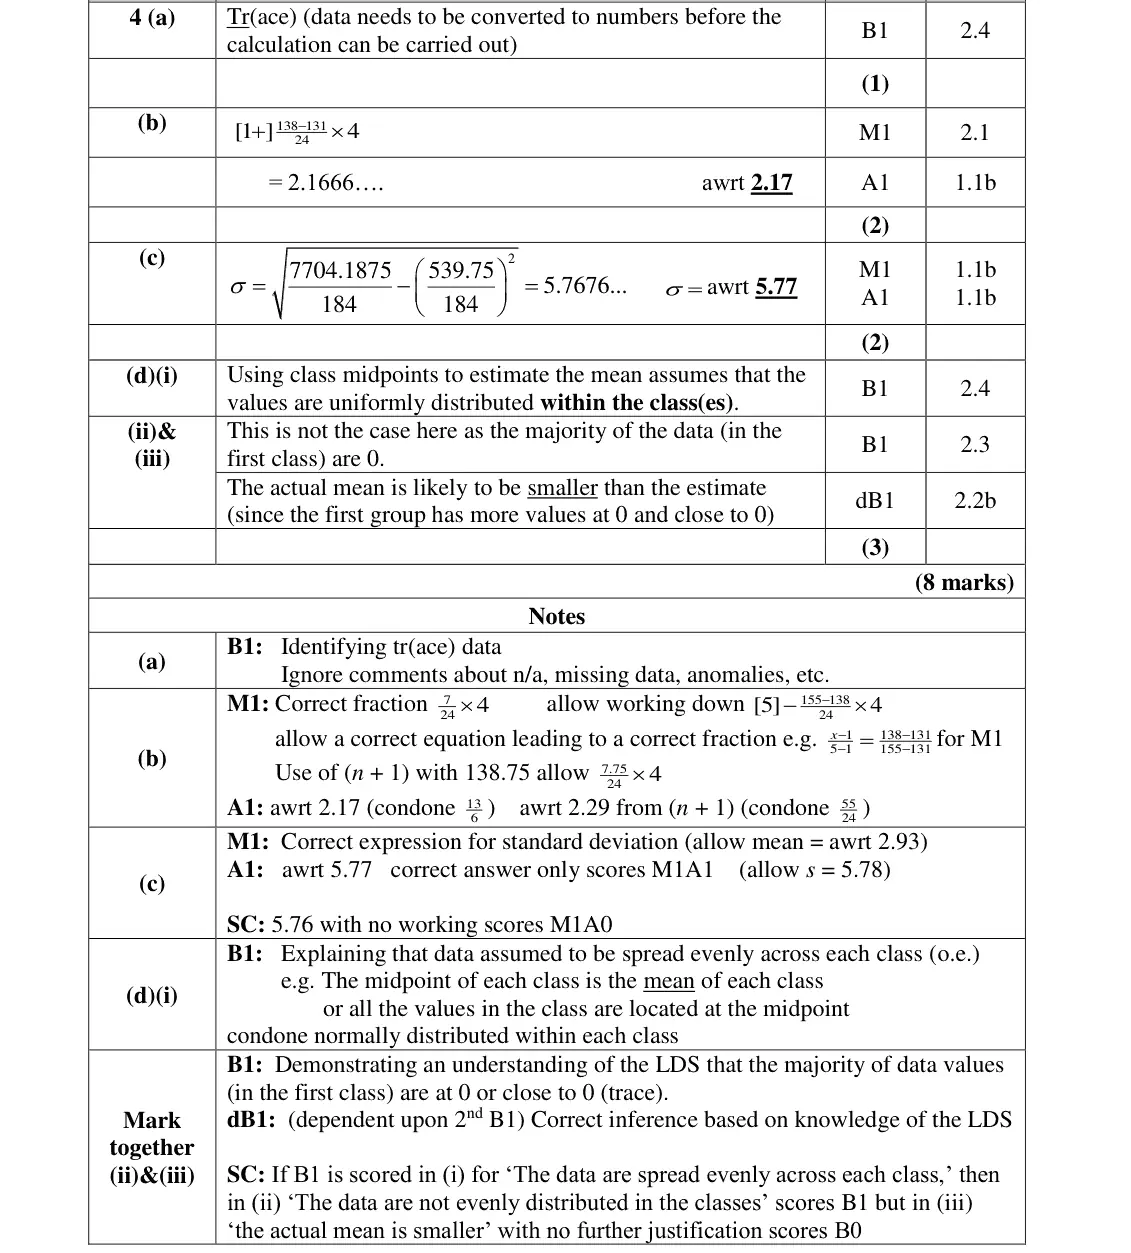
In part (a) most candidates referred to data that was n/a, anomalies or outliers with only a small proportion appreciating that the data set contained trace values for rainfall which needed replacing with numerical values.
Common mistakes
LDS: rainfall includes "tr" (trace, less than 0.05 mm) which must be converted to a number
n/a, missing data or outliers are not the answer
June 2019 · AS Paper 2 (Statistics) · Q4(d)3 marks
Mark scheme (whole question; this part is marked with the orange bar)
Examiner's comment
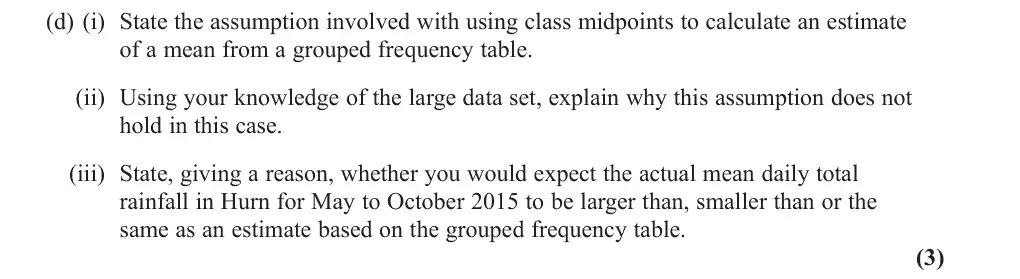
The underlying assumption in part (d)(i) was generally identified but not always with sufficient clarity to gain the mark. Common errors were: ‘data uniformly distributed’ (failing to mention within each class); the average of each class is the midpoint (failing to specify the mean of each class); most of the data is located at the midpoint (failing to identify that the midpoint is assumed to represent all of the data). It was clear from the responses seen here that many candidates have little or no experience with the large data set. In (d)(ii) quite a number referred to the data being based on weather which is unpredictable and that therefore the previous assumption was unrealistic. Good explanations involving the distribution of the bottom class were rare with very few making reference to the majority of data being either 0 or close to 0. Little progress was made in (d)(iii) as many mentioned irrelevancies such as the great storm or the fact that it was during the summer or that the database did not cover a full year. Many did not realise that they were comparing an estimated mean with an actual mean for the same time span and said the actual mean would be higher because the winter months were excluded.
Common mistakes
(i) values are spread evenly within each class (not "data uniformly distributed")
(ii) LDS: most days in the first class have 0 or trace rainfall
(iii) so the actual mean is smaller than the estimate
comparing with winter months or storms is irrelevant
June 2019 · Paper 3 (Statistics) · Q2(a)4 marks
Mark scheme (whole question; this part is marked with the orange bar)
Examiner's comment
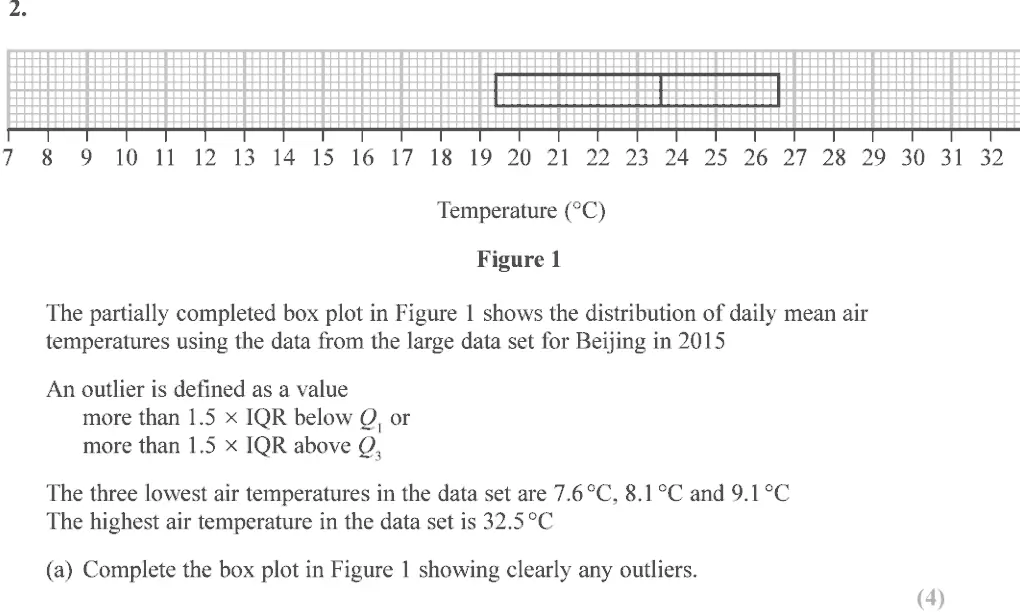
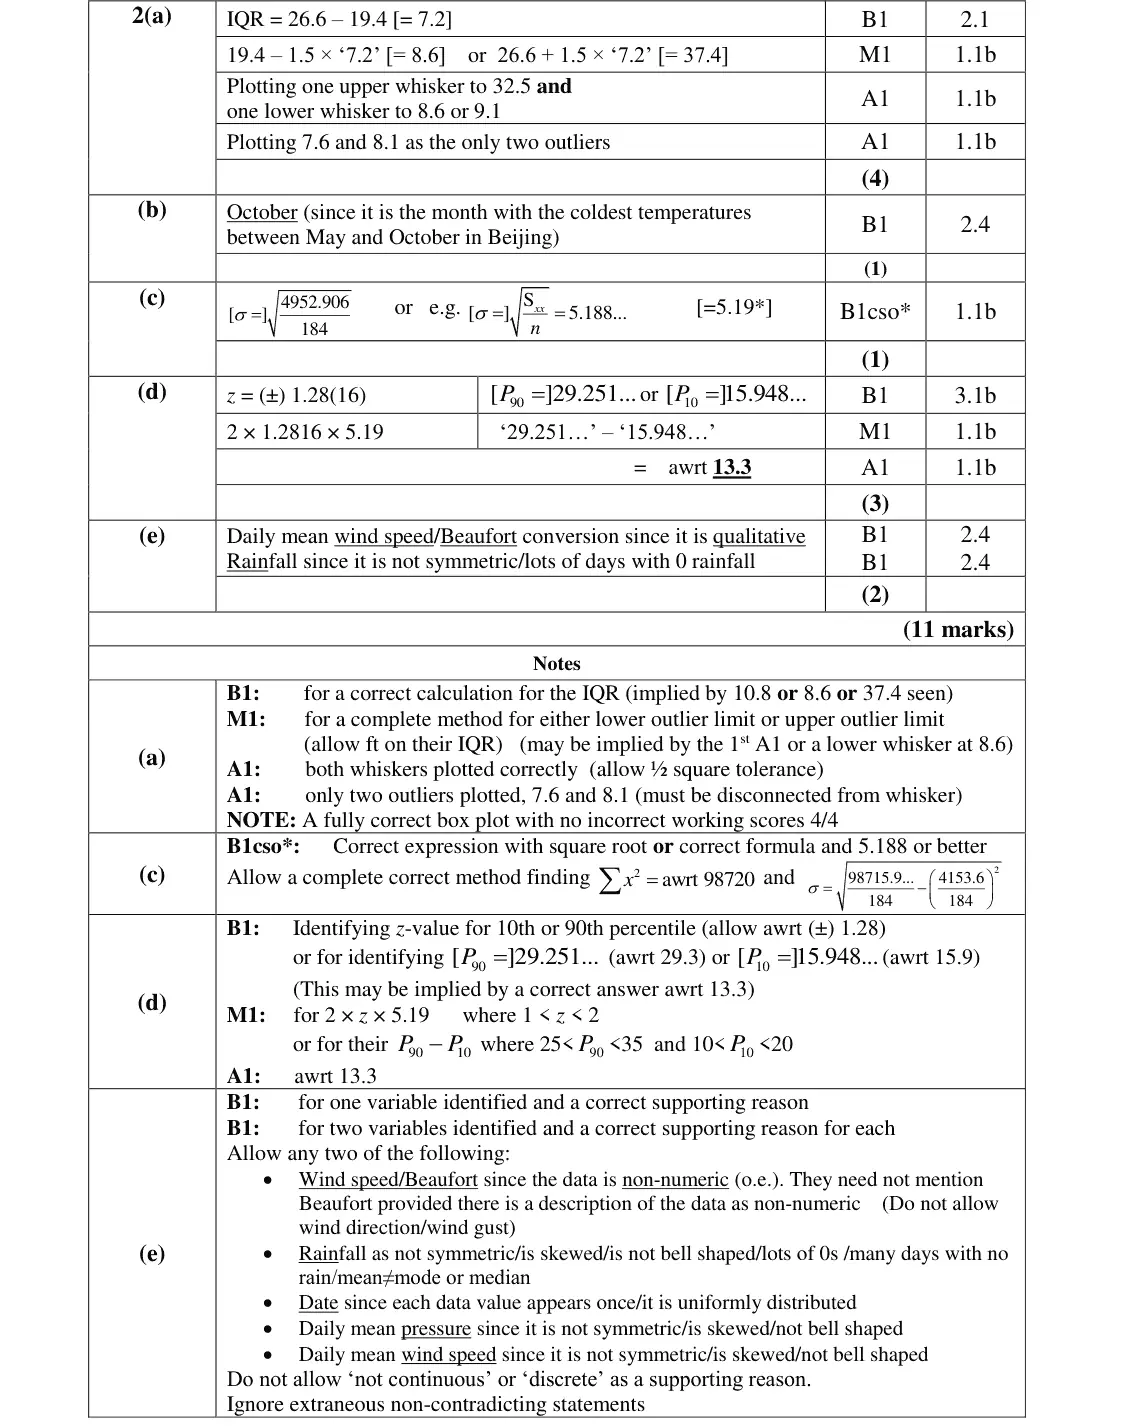
Parts (a), (c) were well attempted by most candidates with part (d) being tackled by more able candidates. Parts (b) and (e) were a problem for those less familiar with the large data set. In (a) most candidates correctly read the quartile values from the diagram to obtain and use the interquartile range to find outlier boundaries. (Where IQR was incorrect it was commonly given as 7.4). Surprisingly there were some inaccuracies in using the formula for outliers even though it was given. Not all candidates showed any working which meant marks could not be awarded if the box plot was not correct. The left hand whisker was commonly drawn to 9.1 (sometimes to 8.6) as required but the right hand whisker was more occasionally incorrect, often extending off the grid instead of stopping at the stated maximum value of 32.5 Usually the two outliers were plotted although they were sometimes omitted by candidates who had shown the correct calculations. Candidates are required to be familiar with the large data set. It was clear from responses in
Common mistakes
IQR = 26.6 − 19.4 = 7.2
limits 8.6 and 37.4
lower whisker to 8.6 or 9.1, upper whisker to 32.5 (not off the grid)
plot 7.6 and 8.1 as the only outliers
show working
June 2019 · Paper 3 (Statistics) · Q2(b)1 mark
Mark scheme (whole question; this part is marked with the orange bar)
Examiner's comment
candidates. Parts (b) and (e) were a problem for those less familiar with the large data set. part (b) that many were not aware that for all locations the data is for the months of May to October only. Successful candidates often explained that Beijing was in the northern hemisphere and so low outliers for temperature were likely to be for winter, and so October. Some candidates perhaps did not read the question carefully enough and stated two months. S Most candidates scored well in part (c), usually using the given formula. A small xx
Common mistakes
LDS covers May to October only
Beijing is in the northern hemisphere so the coldest month is October
give one month only
June 2018 · AS Paper 2 · Q4(a)1 mark
Mark scheme (whole question; this part is marked with the orange bar)
Examiner's comment
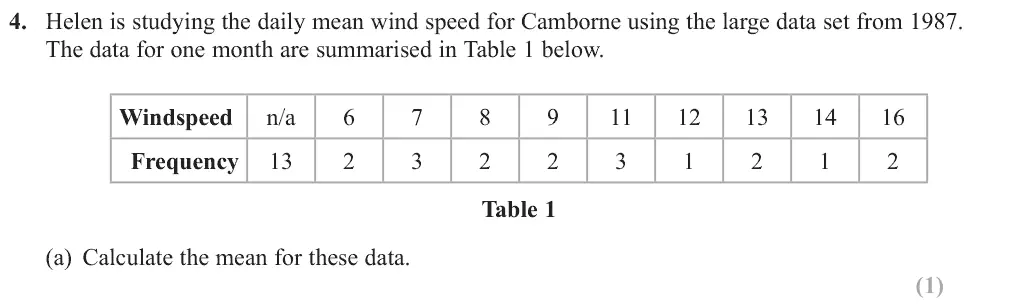
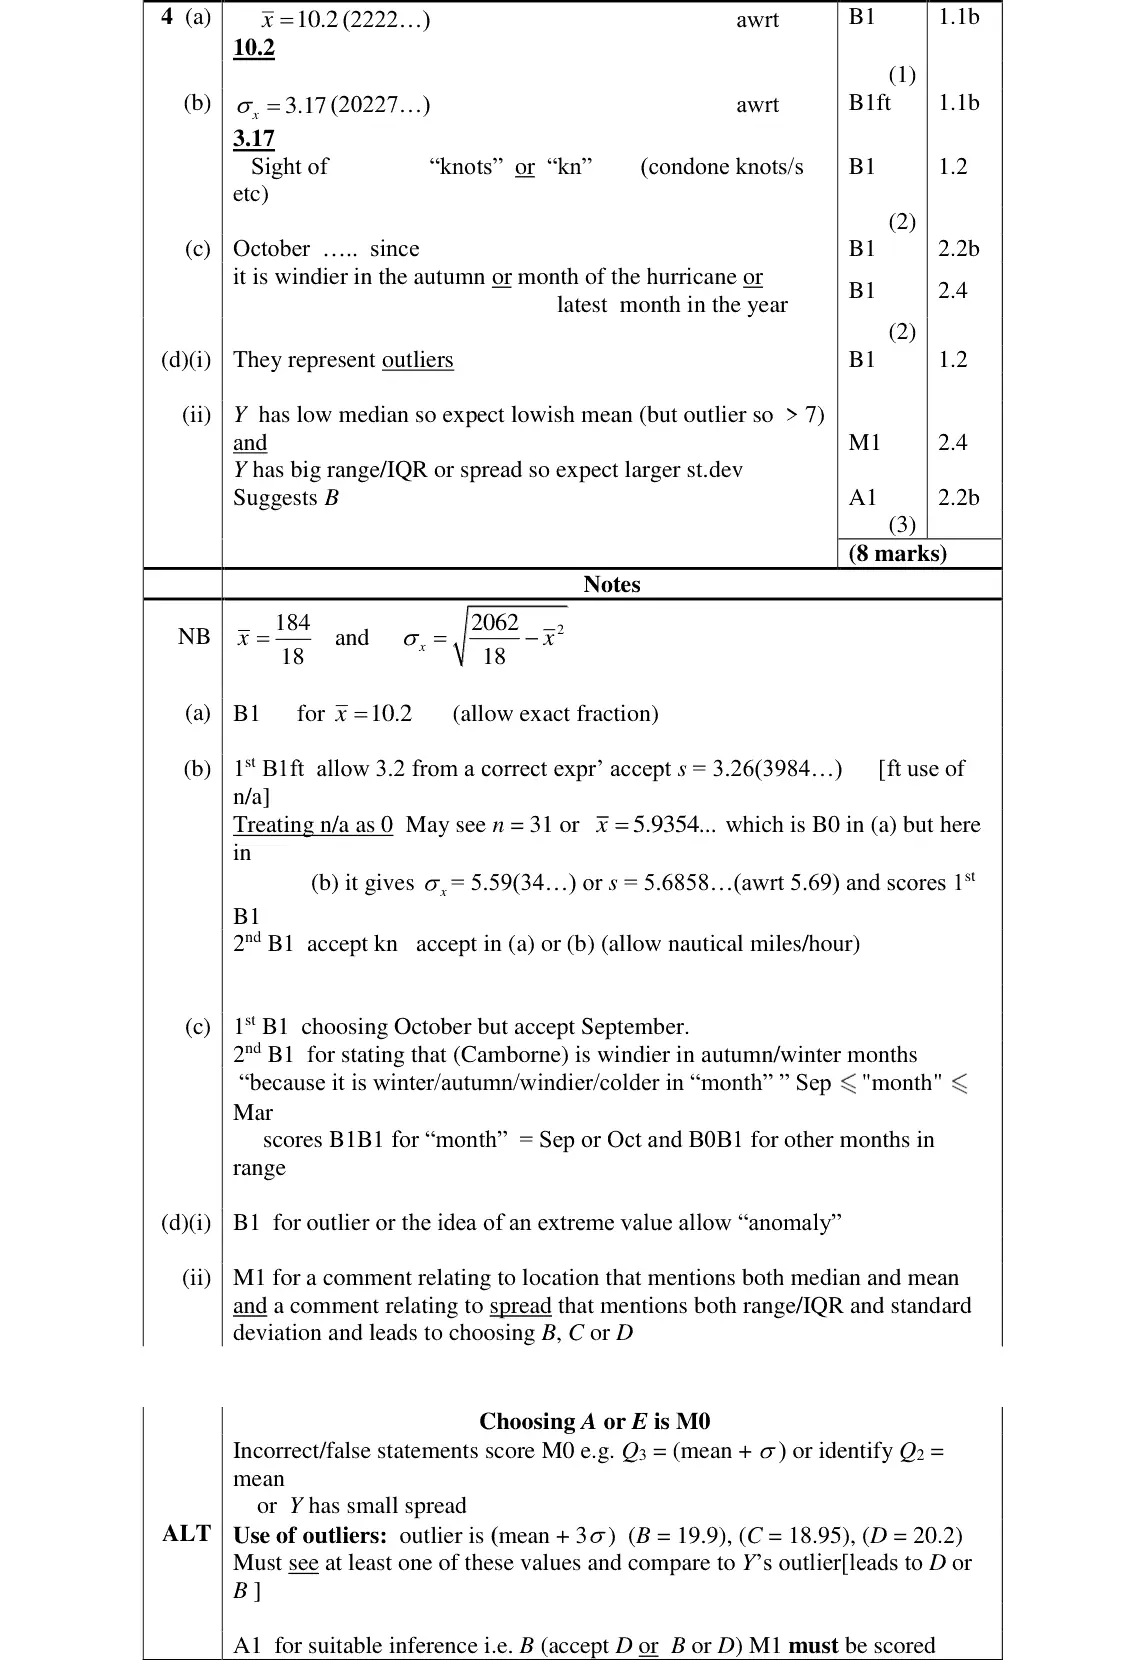
The new specification requires students to be familiar with the large data set and the first part of the question addressed this issue. In part (a) the students needed to realise that n/a in the large data set means that the data for that point was not available and this means that there are only 18 (not 31) pieces of data available. Another skill students are required to have under the new specification is to be able to calculate standard statistics using their calculators. In this case, we expected students to enter the data into their calculator and write down the mean (part (a)) and standard deviation (part
Common mistakes
n/a means data not available, so n = 18 not 31 (treating n/a as 0 gives 5.94)
mean 184/18 = 10.2
use the calculator's statistics mode
June 2018 · AS Paper 2 · Q4(d)3 marks
Mark scheme (whole question; this part is marked with the orange bar)
Examiner's comment
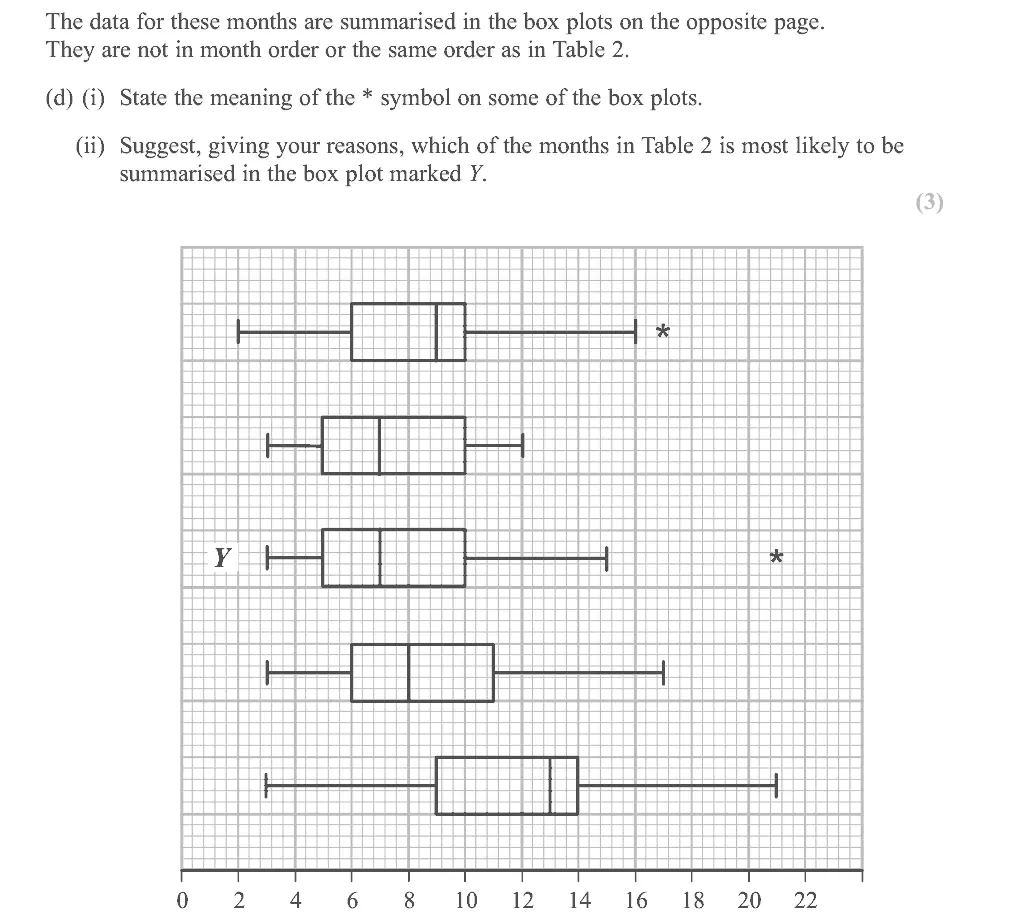
In part (c) there were many good attempts and most students gave a correct response here and in (d)(i) most knew that the * represented an outlier. Part (ii) was very challenging and required some careful thought and inference. Some confused mean with median and assumed that C and D were the 2nd and 3rd box plots in the list since they had the same medians. The intention was that they should identify E as the 5th box plot and A as the 2nd (it has a low mean and standard deviation and clearly has the smallest range on the box plots). Looking at the other 3 they should notice that the range is large and the outlier too would suggest a large standard deviation. The box plot Y has the smallest median of these 3 so a lower mean is suggested which points to B. We were looking for some explanation using correct terminology so we expected references to the mean and median and the standard deviation and a suitable measure of spread from the box plots.
Common mistakes
* marks an outlier
Y has a low median so expect a lowish mean, and a large range/IQR with an outlier so a large standard deviation: month B
do not confuse median with mean
choosing A or E scores 0
June 2018 · Paper 3 · Q4(f)2 marks
Mark scheme (whole question; this part is marked with the orange bar)
Examiner's comment
whole of section A. Part (f) was a familiar type of question from the legacy S1 specification but, although many identified the median and interquartile range as being the preferred statistics to use far fewer gave a reason to support this based on the presence of the outliers.
Common mistakes
outliers (or skew) affect mean and sd so use median and IQR
must give the reason, not just the choice
"skewed so use median" alone is B0
Find an Edexcel maths tutor
Stuck on this? Book a trial session with an Edexcel specialist.